Your AI system should be measured before you trust it. I build it that way.
Djaouad Frih — independent AI engineer. I make retrieval and agents work on the Postgres estates and monoliths that already exist, with a benchmark, an eval suite and a handover doc on every build. Fixed price. Full builds start at $3,500.
Five working days. Scored against your documents. No call required first.
See a benchmark you can rerun →The retrieval eval, the goldset, and the run command are public.
UTC+1 — overlaps EU business hours; 13:00–17:00 UTC US-East overlap
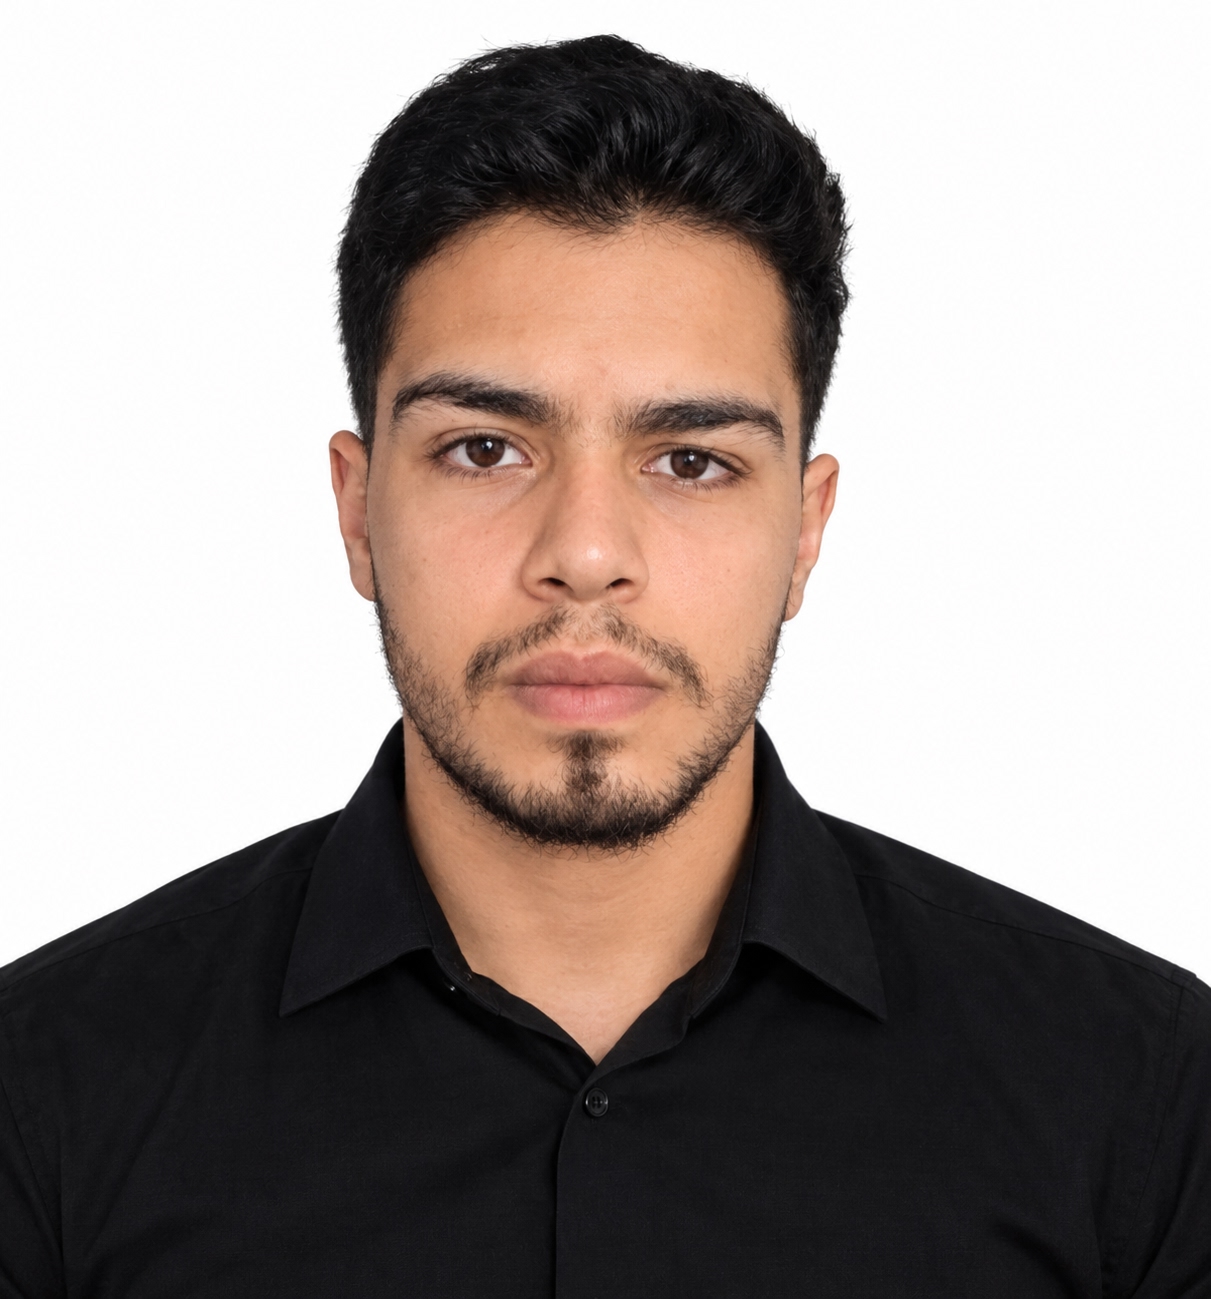
I'm Djaouad, an independent AI engineer. I build the retrieval layer and the agent loop that sits on top of it, plus the production application around the two. The thread through every build is measurement: a benchmark before the first prompt is written, an eval suite that ships in CI, and a handover that leaves you able to rerun both.
I work fixed-price on scoped work — the kind where the spec is written down and the refusal rate is measured against your own documents. If the honest answer is that an existing tool or a subscription solves your problem, I'll tell you that first.
The problems I solve
Your chatbot doesn't know your business.
A demo answers from a prompt. Production answers from your data — with the source attached, a measured refusal rate, and a benchmark showing where it fails.
You can't hire the capability.
AI skills are now the single hardest role to fill globally — 72% of 39,000 employers across 41 countries report difficulty, and AI skills overtook engineering and IT. (ManpowerGroup, 26 Feb 2026)
Your pilot works in the demo and breaks on real traffic.
Real systems need tool-calling loops that terminate, arguments validated before they execute, retrieval measured against a goldset, and a human escalation path with the conversation attached.
You can't tell whether your vendor's AI actually works.
Ask for the eval suite, the refusal rate, the latency distribution and the failure list. If a supplier can't produce them, they haven't measured their system.
Three offers
AI Reliability Audit
Free
Teams shipping AI features who need an independent check before launch.
- Precision/recall/F1 against a goldset built from your corpus
- Refusal rate on out-of-scope questions
- Citation correctness
- p50 / p95 latency and token cost
- Server-side authorization review
Failures are published alongside the scores. Credited in full against any build that follows.
Run the audit →Scoped Build
Full builds start at $3,500
Mid-market teams with a real AI feature ready to ship.
- Production-ready code in your repo, with documentation
- Retrieval benchmarked against a goldset you approve
- Source handed over with a handover call
- Severity-tagged eval dataset gates each deploy
- Fixed price, scoped change orders only
Quoted after a free reliability audit, once the scope is real. No hourly surprises.
Scope a build →White-Label Delivery Capacity
Fixed price, after the free audit
Software and product agencies with signed AI/RAG work and no one to deliver it.
- Production-ready code in your repo or mine, with documentation
- Retrieval benchmarked against a goldset you approve
- Source handed over with a handover call
- Weeklies at your cadence, not mine
- Fixed price, milestone-based
Not a SaaS subscription. Not a template.
Bring capacity to your agency →Selected work
Every item below is my own project. Two run on my own infrastructure. None of them is client work — and I'm not presenting them as client work.
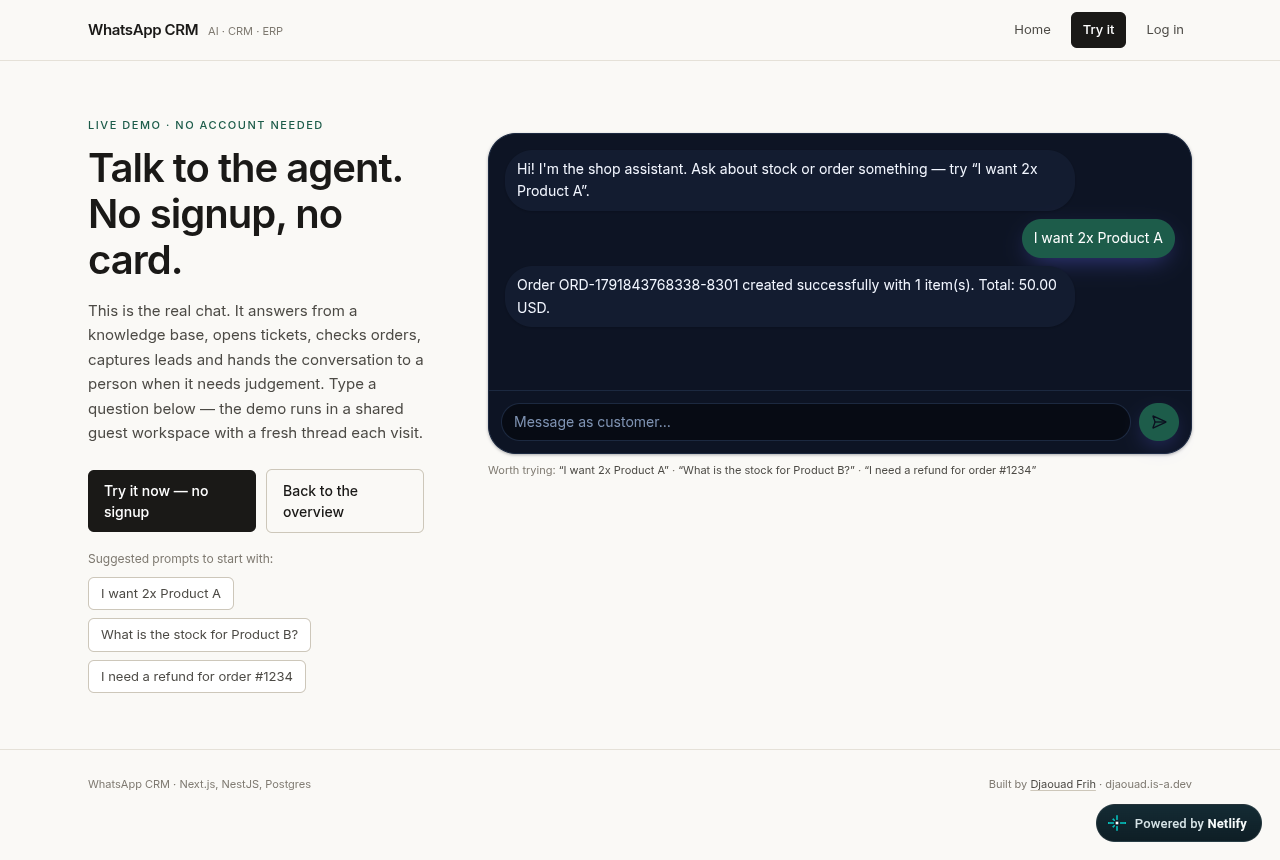
Agent reads WhatsApp, checks real stock, creates orders — behind human approval gates with an audit trail.
No customer. No published agent benchmark — 2 committed test files.
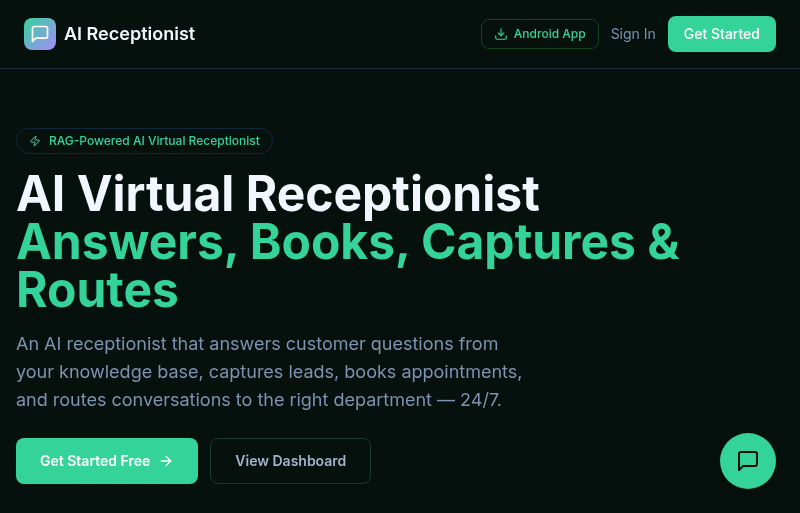
Answers questions, books appointments & captures leads from your own docs. 232-query retrieval benchmark.
Single-tenant, single-language. FPR 76.9% at the F1-optimal threshold.
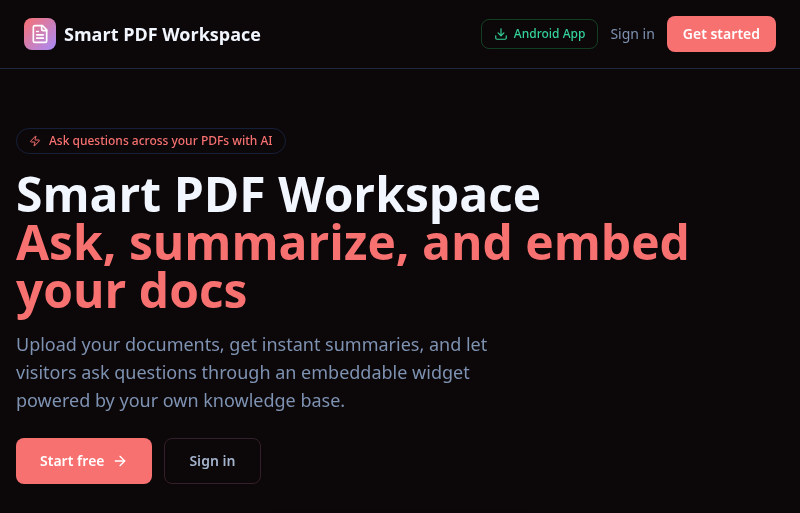
Ask your contracts, invoices & PDFs. Answers with sources, and the retrieval mode that produced each one.
Text layer only, no OCR. No published retrieval benchmark.
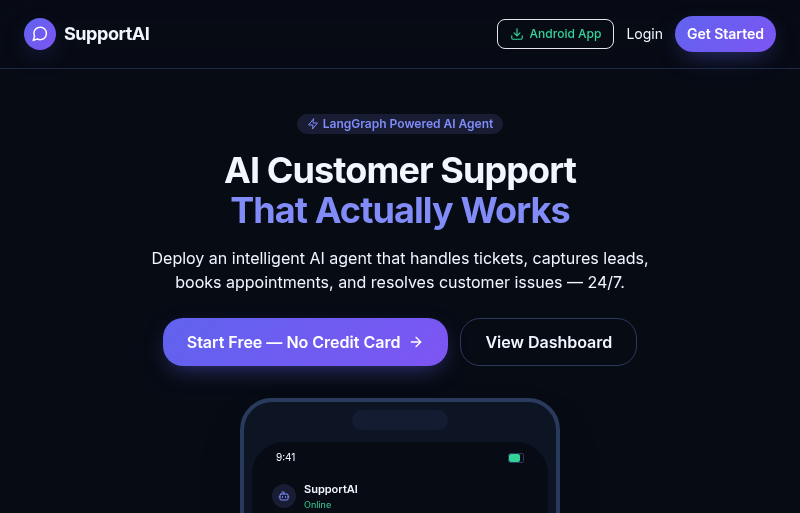
Handles support, creates tickets & escalates to humans — schema-validated tool calls.
No published retrieval benchmark. 2 committed test files.
More work & the benchmark
More of my projects and the public retrieval benchmark.
The parts you can open
- Public repositories
- ~214 commits across three main repositories
- CI on every push
- The failing runs are the interesting ones.
- Committed test suites
- 13 test files in the receptionist backend, 2 in the support agent backend
- Versioned eval datasets
- 69-case conversation dataset, 97 turn assertions, 15 categories, severity tags that gate a deploy
- Retrieval benchmark
- the retrieval benchmark
- Codebase
- ~24,000 lines of TypeScript
- Measure first. A retrieval + authorization audit runs on your documents and the scores are published before any code is written.
- Scope with acceptance criteria. We write the spec, the goldset, and the deploy-gating severity tags together.
- Build the loop. Retrieval + agent + application, tested against the goldset on every push.
- Evaluate before ship. Precision/recall/F1, refusal rate, citation correctness, and latency/token cost are published with the build.
- Hand over. Source, infra credentials, and a handover doc land in your repo; your team reruns the benchmark.
- Defend the window. A scoped defect window, change orders only, no surprises.
How an engagement runs
- 01
Reliability audit
Five working days, scored against your documents. No call required first.
- 02
Fixed-price scope
The audit becomes a written spec with acceptance criteria and a deploy-gating eval.
- 03
Build at your cadence
Weekly handoffs. Source in your repo. The benchmark is yours to rerun.
- 04
Handover + defect window
Docs, credentials, and 30 days to find defects.
Audit five working days · scoped build 3–6 weeks · production system 6–12 weeks.
Every inquiry gets a reply within one business day — including "this isn't for you".
Two clients, two countries, and what they actually hired me for
Both were website builds, not AI systems. I'm not going to present them as something they weren't.
“Great people, very good service. Made my website within 2 weeks in such a professional manner, very good communication skills — would highly recommend!”
“Huge shout-out to Djaouad! Complete, fully functional full-stack build delivered right on schedule. That's how it's done. Star developer right here.”
What they establish is the thing no screenshot on this page can: someone working remotely from Algeria delivered on schedule, twice, for real businesses in two countries.
Happy to arrange a reference call — ask on the call and I'll connect you directly.
What I don't do
- I'm not a full-service digital agency.
- I don't take work where I'm the cheapest credible option.
- I don't start engagements without written scope and acceptance criteria.
- I'll tell you if your project is a SaaS subscription rather than a build.
Start with the audit, not with a sales call.
If your AI system is answering before it's measured, it's answering from a guess. The free reliability audit is five working days, scored against your own documents, and you keep the report either way — including the line that says you don't need AI here yet.
Djaouad Frih.
contact@djaouad.is-a.dev